OmniHuman 2.0 speech demonstration excerpt
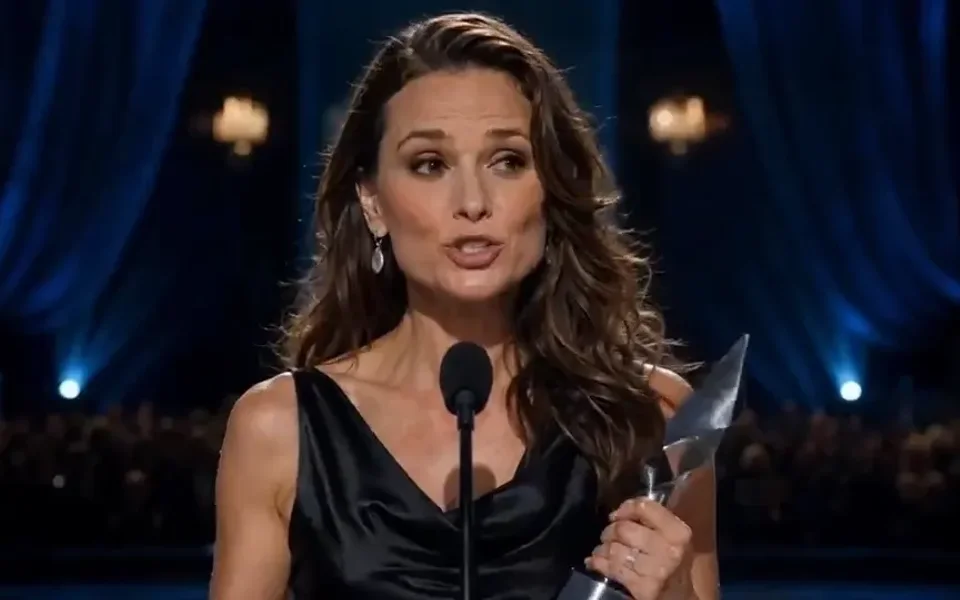
Model output documented by the source.
omnihuman2.org
No videos generated yet
Enter a prompt and click Generate to create your first AI video.
OmniHuman 2.0 generates talking-avatar video from a portrait image and audio. BytePlus's published tooling documents a separate Vision AI task workflow, so it should not be treated as an interchangeable generic text-to-video endpoint.
Model output documented by the source.
omnihuman2.org
The references below identify the sources for this model’s capabilities. Confirm current access, request limits and pricing with your service provider before integration.
Where do OmniHuman 2.0 specifications come from?Review generated results before use. Available modes and request limits depend on the service you choose; check the linked documentation before integration.